

Deploy a standalone collector
This is the operator walkthrough for standing up a standalone collector — the dial-out container you deploy near the devices it collects. It exists for two reasons: it reaches a network the core cannot, and it does the work there, holding the hundreds of slow device sessions at the site and handing the core only the finished, scrubbed result. It keeps no database: its durable state is its own identity and an outbox of results not yet acknowledged.
If the core reaches your devices comfortably and is not spending its time waiting on them, you don’t need this — use the built-in embedded collector.
A standalone collector dials out to the core, so the site it lives in needs outbound reachability to the core and nothing inbound — no ports opened toward the collector or the site.
The whole deployment is one command, and the core writes it for you. Everything below is the two minutes of clicking that produces that command, and the proof that it worked.
Before you start
Section titled “Before you start”- A host at the site that can run the collector container (Docker), with outbound network access to the Taranac core’s API — or a Taranac appliance, which installs the collector from images already on its disk.
- RBAC permissions on the core:
collectors→ create to add the collector, andncm_devices→ edit to issue its enrollment token (and to revoke its identity later). - Local reachability from that host to the devices you want to collect, over SSH/SCP.
- If a proxy, load balancer or firewall sits between the site and the core, it must
tolerate an idle HTTPS request of about half a minute. The collector’s job poll is a
held long-poll — the core keeps the
GETopen for roughly 25 seconds, sending nothing, and answers the instant work appears — so a middlebox that cuts idle connections sooner will sever it. Nothing breaks if it does: the collector falls back to its slow poll interval on its own. You simply lose the near-instant pickup that makes Collect now feel immediate.
Step 1 — create the collector on the core
Section titled “Step 1 — create the collector on the core”In the core UI, go to Settings → System → Collectors and choose New Collector.
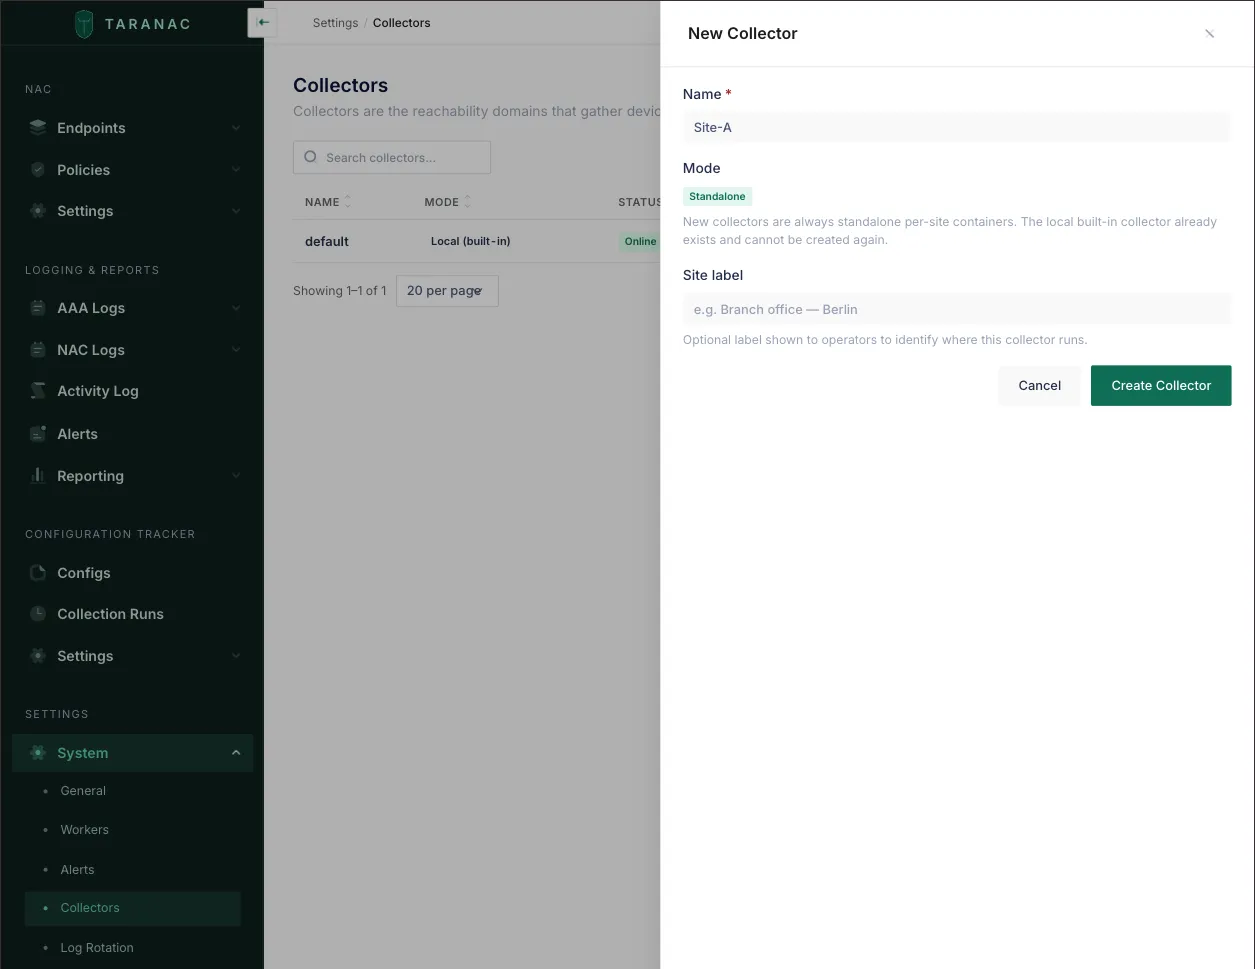
Give it a Name, and optionally a Site label — free text for humans, because the core never calls the collector and this is just where you note where it lives. Mode is fixed at Standalone: the local built-in collector already exists and cannot be created again.
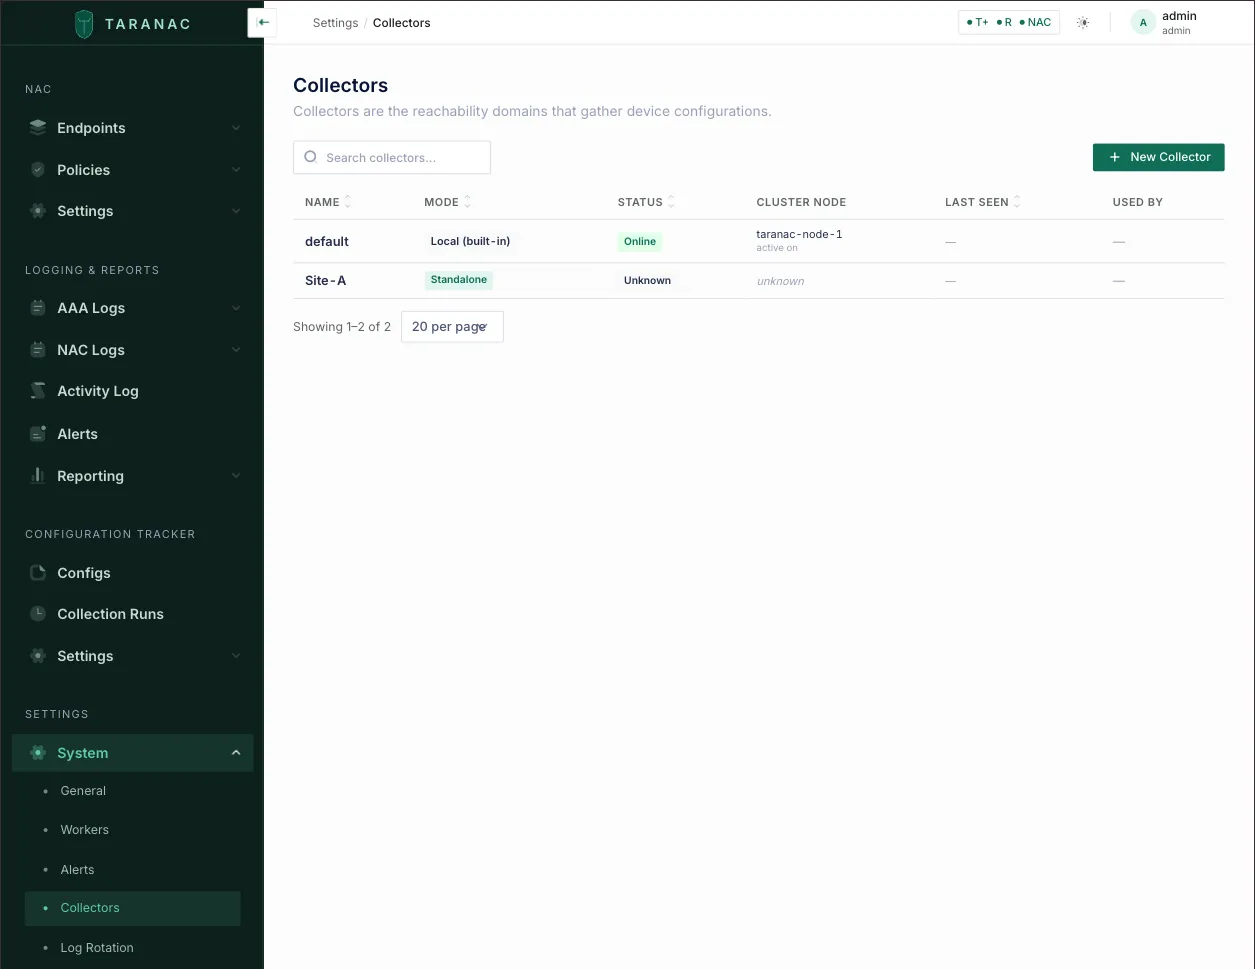
It starts life with status Unknown, because it has not reported in yet:
Step 2 — issue a reveal-once enrollment token
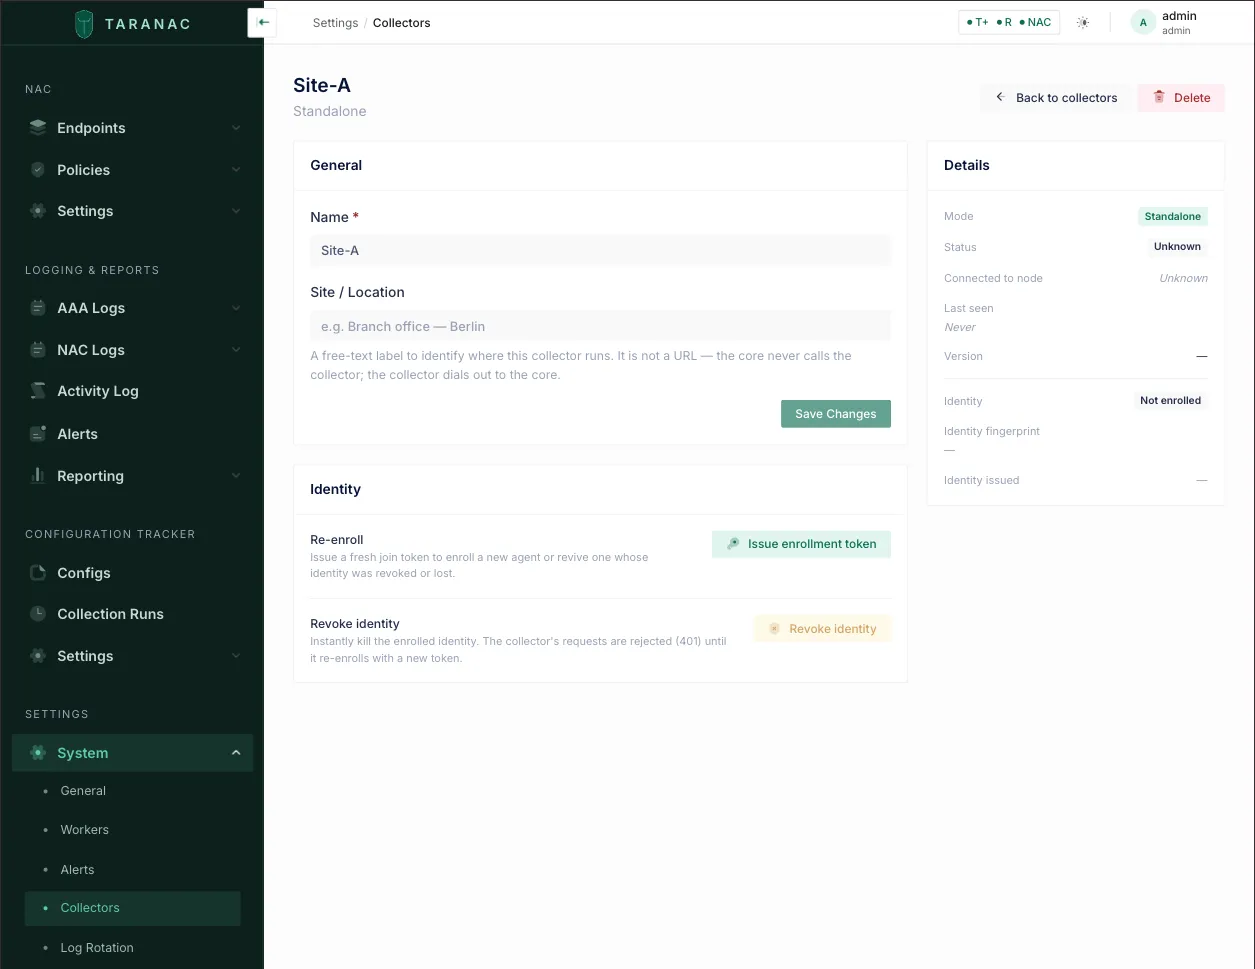
Section titled “Step 2 — issue a reveal-once enrollment token”Open the new collector. Its detail page carries the identity controls, and the Details rail on the right is where you will watch this deployment land — right now it reads Not enrolled, Never seen, no fingerprint.
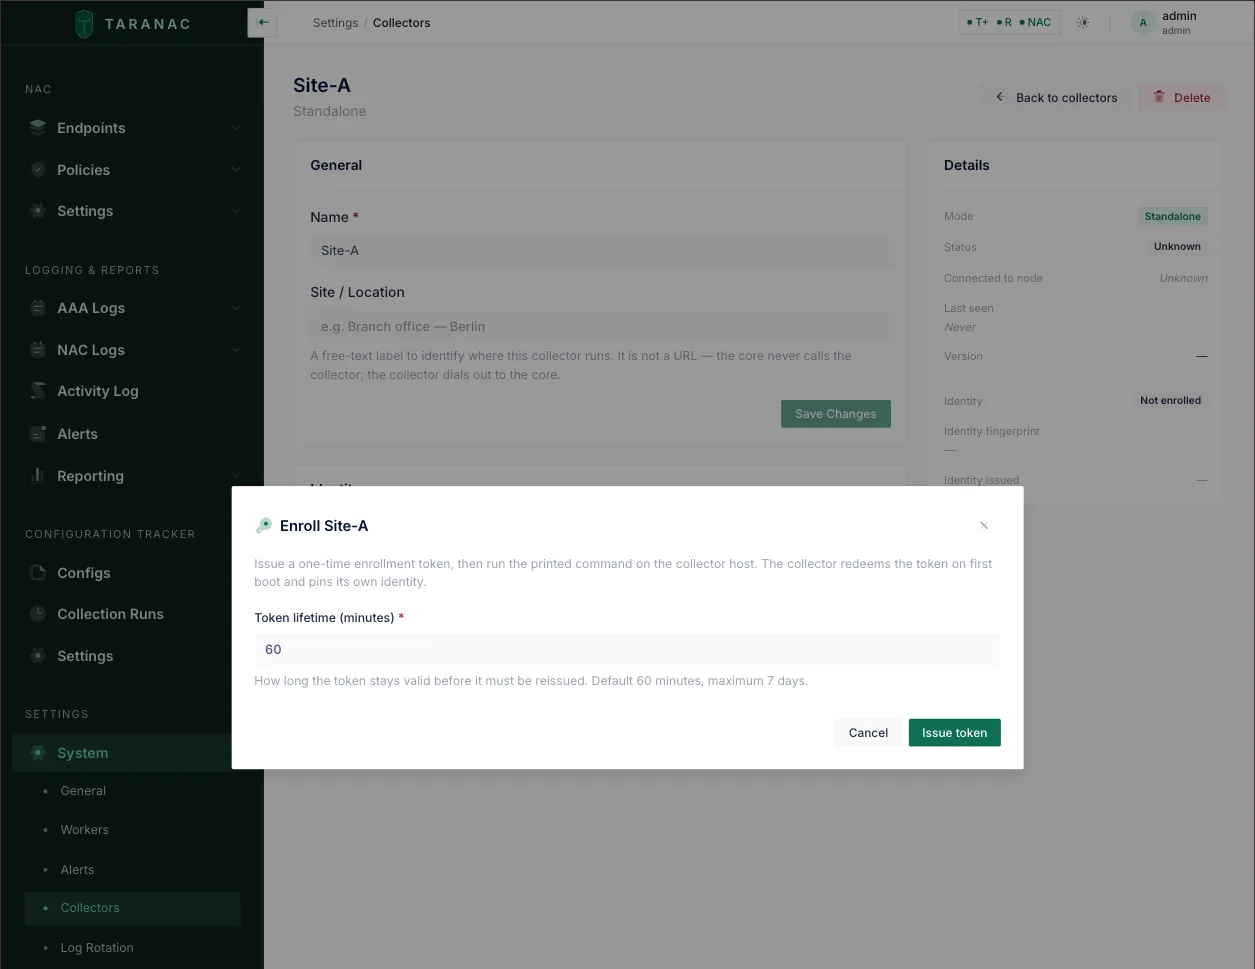
Choose Issue enrollment token. The dialog asks one thing — how long the token stays valid. The default of 60 minutes is long enough to walk to the other host and short enough to limit exposure; the maximum is 7 days.
Then it shows, once: the token, the core’s URL, and a ready-to-paste join command with both already filled in.
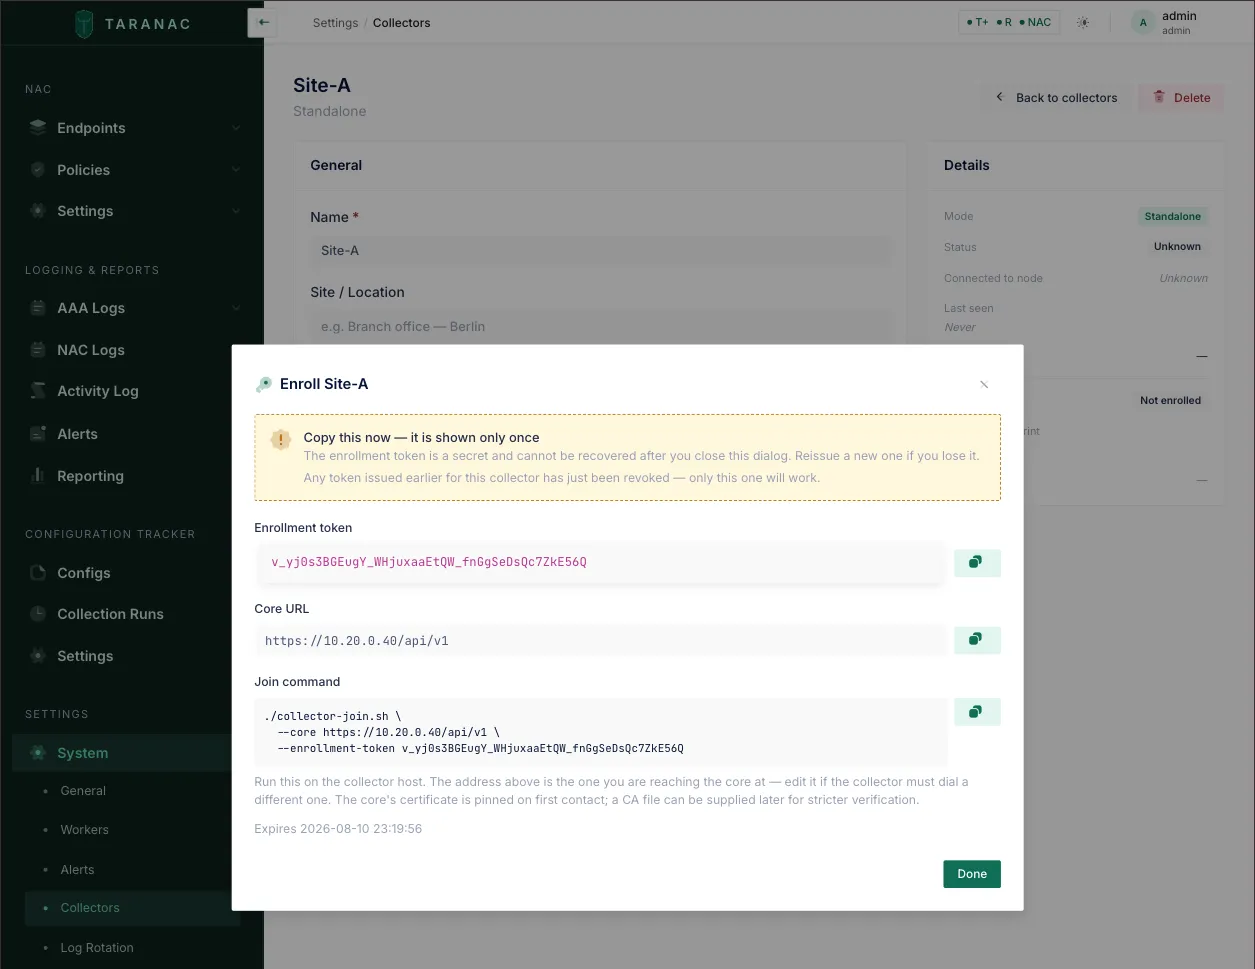
Two things about that command are worth knowing before you copy it:
- The address is the one you are reaching the core at right now, derived from your own
request — so it is demonstrably an address that works, rather than a placeholder or a
PUBLIC_BASE_URLthat drifted months ago. It is editable, because a collector on a segmented site may have to dial the core by a different name than the browser you issued the token from. Edit it here, before you copy. --coremust include the/api/v1prefix. The request signature covers the full path, so a missing prefix means every signed poll fails authentication.
Step 3 — run the join on the site host
Section titled “Step 3 — run the join on the site host”On the site host, run the command from the dialog in the unpacked bundle directory:
cd /opt/taranac./collector-join.sh \ --core https://10.20.0.40/api/v1 \ --enrollment-token v_yj0s3BGEugY_WHjuxaa…On a Taranac appliance the same install is driven by the module installer instead —
sudo taranac-module collector, run over SSH. The first-boot console wizard
deliberately hands over rather than asking a 32-character token to be typed at a
hypervisor console. It asks for the pair the dialog shows together, the core URL and the
token, plus a poll interval (default 30 seconds), and it installs from an image
already on the appliance’s disk — it never reaches for a registry.
The script writes the collector’s configuration beside itself, starts the container, and then waits until the collector has actually attached before reporting success:
collector-join: writing collector.env, enrollment-token…collector-join: starting the collector…[+] up 3/3 ✔ Network taranac-collector_default        Created ✔ Volume taranac-collector_collector_state Created ✔ Container taranac-collector              Startedcollector-join: waiting for the collector to attach to the core…
collector-join: the collector is attached to https://10.20.0.40/api/v1.  Trust:       pinned on first contact (the fingerprint appears in the log below)  Core UI:     NCM -> Collectors — it is there now.
That wait is the point: if the collector did not attach, the script prints the daemon’s own reason and exits non-zero, instead of leaving you with a container quietly restart-looping and a green “done” on your screen.
Under the hood, on first boot the collector:
- Generates its own Ed25519 identity key and persists it locally (private key, mode-restricted, never leaves the box).
- Redeems the one-time token against the core, which pins the collector’s public key as its identity.
- Deletes the token (it’s spent) and starts long-polling the core for work.
From here every request the collector makes to the core is signed with its Ed25519 key and timestamped — there’s no long-lived shared secret on the wire.
Two commands to keep for later:
docker compose --env-file .env.collector -f docker-compose.collector.yml logs -f collectordocker compose --env-file .env.collector -f docker-compose.collector.yml psThe join writes two files beside the compose file and they do different jobs, so don’t
be surprised by either. collector.env is the daemon’s own configuration — the core URL,
the trust choice, the poll cadence — and is the one you may edit. .env.collector is
compose interpolation only (the image tag, and the CA bind-mount source when you supply
one); it exists so the install never writes the bundle’s own .env, which belongs to a
different stack. That is why every compose command above carries --env-file .env.collector.
The options you rarely need
Section titled “The options you rarely need”Everything else collector-join.sh accepts at install time:
| Flag | What it does |
|---|---|
--ca-file <path> | verify the core against a PEM CA bundle instead of pinning — see Trust modes |
--trust-any | verify nothing. Lab only; this channel carries device credentials |
--collector-id <label> | a display label for this container. Cosmetic |
--poll-interval <seconds> | the loop’s floor between job polls — used when it is backing off, since a healthy poll is held open by the core. Default 30, minimum 5. Widening it also widens the container’s health window, so a slow site does not read unhealthy while collecting perfectly |
COLLECTOR_IMAGE=<image> (environment) | run an image already on this host instead of the published one for this version — the air-gapped case |
--ca-file and --trust-any contradict each other and the script says so. Every remaining
flag is an operation on an installed collector — --status, --update, --uninstall,
--reset-trust — and they are covered below.
Step 4 — verify it’s online and assign work
Section titled “Step 4 — verify it’s online and assign work”Back on the core, the collector’s page answers for the whole deployment:
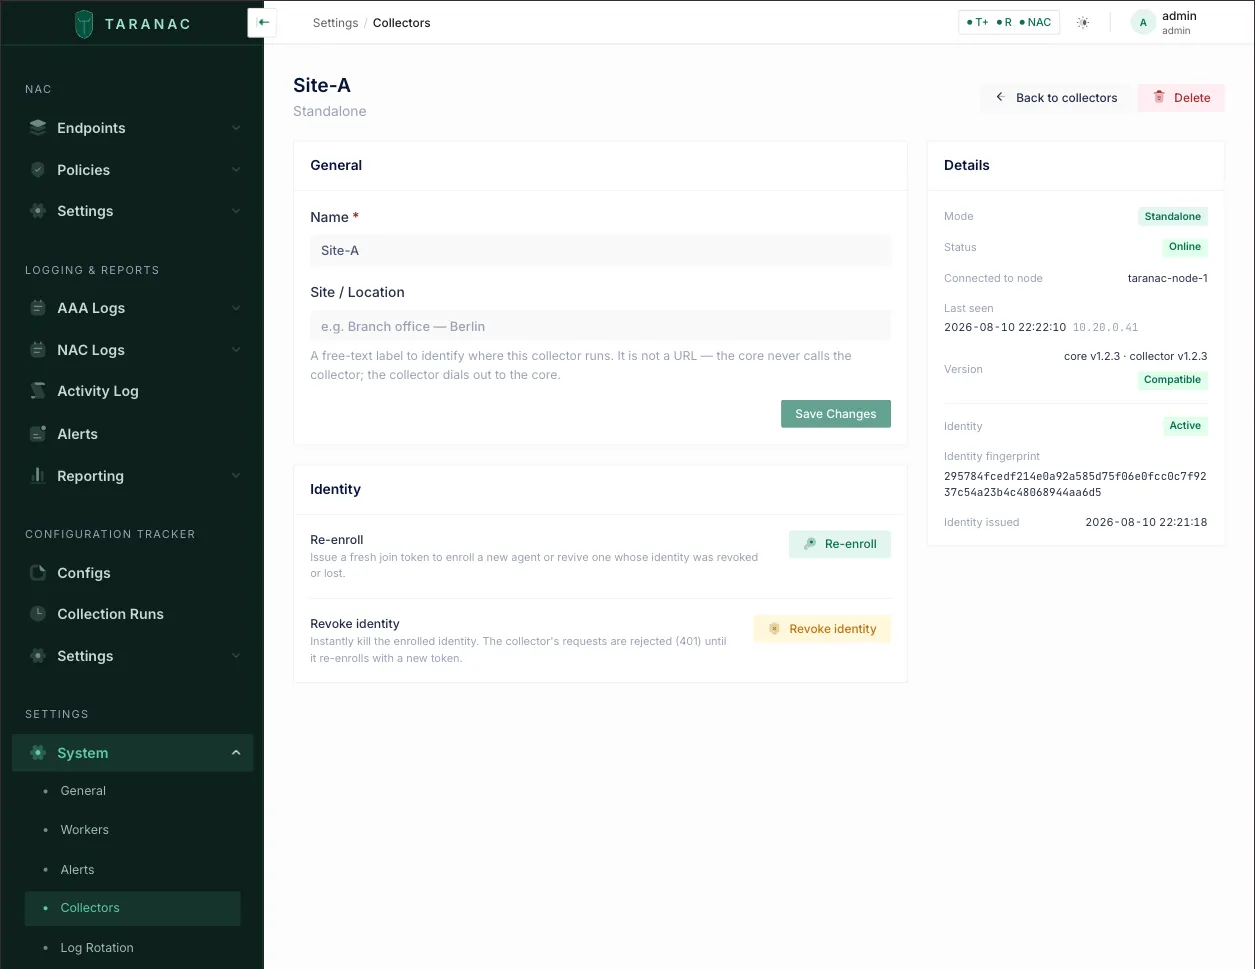
| What it says | What it means |
|---|---|
| Status: Online | It has reported in within the staleness window |
| Connected to node | Which cluster node this collector talks to. Under HA there is no shared client-facing address, so each collector talks to exactly one node — and when a collector goes quiet, this is what tells you whose outage explains it |
| Version · Compatible | The core’s version and the collector’s, and whether they agree |
| Identity: Active + fingerprint | The public key the core pinned at enrollment, and when it was issued |
Then put it to work:
- Set the collector field on the sources for that site (or bulk-onboard the site’s devices with this collector selected).
- Use Collect now on a config to confirm end-to-end reachability, then check the version rail for the first snapshot.
Trust modes
Section titled “Trust modes”The collector verifies the core one of three ways. The default is the middle one, and the right answer for almost everyone.
| Mode | How to get it | What it means |
|---|---|---|
| Pin (default) | nothing to do | The certificate presented on first contact is the only one accepted afterwards. A later change is refused and named, not silently accepted |
| CA | --ca-file /path/ca.crt | Verify against a PEM CA bundle instead. The strictest mode. Behind an nginx edge this is the edge’s CA, not the core’s |
| Any | --trust-any | Verify nothing. A lab setting — this channel carries device credentials, so do not ship it |
On an appliance, the CA mode is sudo env COLLECTOR_CA_FILE=/path/ca.crt taranac-module collector.
When the core’s certificate is legitimately replaced, the collector refuses the new one and prints both fingerprints — a pin that re-learns itself on every restart protects nothing. Re-pinning is a deliberate one-shot:
./collector-join.sh --reset-trust # on a Docker hostsudo taranac-module collector --reset-trust # on an appliancePersistence — what must survive a restart
Section titled “Persistence — what must survive a restart”The collector keeps a small amount of durable state on a named volume that must persist across container restarts and image updates:
- its identity (the Ed25519 private key, public cert and fingerprint), and
- its outbox — the local, durable store-and-forward buffer of results not yet acknowledged by the core.
The outbox is what makes a brief link outage or a restart safe: buffered captures are re-delivered idempotently, so nothing is lost and nothing is double-written. It is bounded, though — past 10,000 buffered results the collector stops claiming new work and says so, while the uploader keeps draining to relieve the pressure. A very long outage therefore pauses collection rather than growing a queue without limit. If you destroy that volume, the collector loses its identity and must be re-enrolled.
Note the collector stores no device credentials at rest — those are handed to it just-in-time per collection and used only in memory.
Rotating and revoking identity
Section titled “Rotating and revoking identity”- Rotate / re-enroll — issue a fresh token from the collector’s page and re-run the join on the host. Supplying a new token to a box that is already enrolled re-attaches it: the daemon rotates its keypair and enrolls again.
- Revoke — from the collector’s detail page, Revoke identity invalidates its key immediately; the next signed request it makes is rejected with a 401, and after five consecutive rejections the daemon halts into a re-enroll required state rather than inventing a new identity for itself. Buffered outbox results are kept and re-ingest once it is re-enrolled. Use this if a site host is decommissioned or compromised.
Ask it what it is doing, or remove it
Section titled “Ask it what it is doing, or remove it”Both answers come from local state only, deliberately: this is what you run when the core is the thing you suspect, and a status command that hangs on the connection under investigation is worse than none. Neither makes a network call.
On a Docker host, in the bundle directory:
./collector-join.sh --status # where it points and what trust mode it uses, # the container's state and health, whether it # is enrolled (key-id), the pinned core-cert # fingerprint, how long ago it last polled, how # many results are waiting in the outbox, and # the last error SINCE IT LAST STARTED./collector-join.sh --uninstall # container, state volume and config files./collector-join.sh --uninstall --force # …discarding a non-empty outboxOn an appliance:
sudo taranac-module --list # what is installed on this boxsudo taranac-module collector --status # the same local answer, minus the # outbox count and the trust linesudo taranac-module collector --uninstall # containers and volumes, cleanlysudo taranac-module collector --uninstall --force“Since it last started” is not a detail: a collector that failed twice and then attached is healthy, and reporting its last historical error as the current state is exactly the stale answer these commands exist to stop giving.
Two things about removal:
- The outbox is checked first. If it still holds results the core has not accepted, the
uninstall refuses and says how many. Those results exist nowhere else — the devices
were read here and the configurations went no further — so let it drain (it retries on
its own) or accept the loss explicitly with
--force. - It is local. Neither command deletes the collector on the core. A box being decommissioned frequently cannot reach the core any more, and an uninstall that fails exactly then is not an uninstall — so the two halves are independent, and each reminds you of the other. Delete the row yourself under Settings → System → Collectors, or it sits in the list for ever as offline.
Keep the collector in step with its core
Section titled “Keep the collector in step with its core”The collector image and the core must agree on the snapshot contract — how a config is scrubbed, hashed and fingerprinted. If they diverge, the core fail-closes that collector: it dispatches nothing and ingests nothing until the two match again. The Version row on the collector’s page is where you see the two side by side; the mechanism, and why idling is the correct outcome, is on the Collectors page.
Three consequences worth carrying into the field:
- It is not scoped to whatever changed. A skewed collector stops collecting for every tracked config it serves, not only the ones touched by the change that moved the contract.
- A refused poll is not a heartbeat. The contract check runs before the core gets far
enough to stamp
last_seen, so a fail-closed collector also stops reporting in: within 15 minutes it reads Offline and raises the ordinaryncm_collector_offlinealert. Locally the same thing surfaces as anunhealthycontainer, because the daemon only touches its liveness file on a poll that actually succeeded. - So a collector that “went offline” right after an upgrade is usually a contract skew,
not a dead host or a broken link. Check its log for
version mismatch (409)before you go hunting a network fault.
1.2.6 moved the contract, because the two masking switches on a scrub set and a recipe changed what a snapshot is identified by. Every standalone collector still on an older image fail-closes the moment its core passes that line, whether or not any of its configs use those switches — so plan the collector upgrades into the same maintenance window as the core upgrade. Recovery needs no re-enrollment: the collector keeps slow-polling while refused and resumes on its own the moment the images agree again.
The cure
Section titled “The cure”./collector-join.sh --update # move it to the version its CORE runs./collector-join.sh --update --check # is it behind? report only, change nothing--update asks the core, never a public release feed. A collector must match its own
core, so “update to the newest release” is precisely wrong while you upgrade hosts one at a
time — and a remote site can always reach its core (that is its whole job) while it often
cannot reach the internet at all. The core reports its version on every authenticated
answer and the daemon records it beside its identity, so this reads local state and opens
no extra connection. It then pulls the matching image, swaps it in, waits for the collector
to attach — and rolls back to the previous version if it does not come back, because a
remote collector that fails to start is one nobody is standing next to.
Two more forms, for when the core cannot be consulted:
./collector-join.sh --update --version 1.2.8 # move to a version you name./collector-join.sh --update --from ./image.tar # docker load an image tarball firstOn an appliance there is no --update. The module installer never downloads anything —
every image it can use is baked into the golden disk — so moving an appliance collector
means having the matching image on that box and installing the module again with a fresh
token, naming the image if it is not the appliance’s own version:
sudo env COLLECTOR_IMAGE=<image> taranac-module collectorThe trap — ./taranac update does not move a collector
Section titled “The trap — ./taranac update does not move a collector”On a collector host the bundle’s familiar ./taranac update refreshes the bundle files
only — this script, the compose file, the docs — and leaves the container alone. That
is deliberate, it says so as it finishes, and it points at collector-join.sh --update. A
collector follows its core, not the newest release.
The rest of the wrapper follows the same rule. On a collector host ./taranac ps and
./taranac logs -f collector drive the collector’s stack, while the subcommands that
need a database and an API — cluster …, unlock, reset-password, create-admin,
installation-id, reset — refuse with an explanation and a list of what this host can
do, instead of a wall of “variable is not set” warnings ending in “service api is not
running”.
Troubleshooting
Section titled “Troubleshooting”| Symptom on the core | Likely cause | Fix |
|---|---|---|
| Status stuck Unknown | Collector never enrolled / never started | Re-run the join; check the host’s outbound access to the core. If collector-join.sh exited non-zero, its message names the cause. |
| Join fails authenticating every poll | --core missing the /api/v1 prefix | The signature covers the full path. Re-run with the prefix; the script warns when it looks absent. |
| Status Offline shortly after a core upgrade | Contract skew — the refused poll never reached the heartbeat | ./collector-join.sh --update. Its log will show version mismatch (409). |
| Status Offline after working | Host down, link down, or container stopped | Restart the collector; confirm outbound reachability. --status answers without the core. |
| Log says the core’s certificate changed | The core’s certificate was replaced — or something is impersonating it | If you replaced it, --reset-trust. If you did not, stop and find out why before re-pinning. |
| No work dispatched, nothing ingested | Version mismatch (fail-closed) | ./collector-join.sh --update. It idles for every config it serves until the images agree. |
Container reads unhealthy while the daemon looks alive | Only a successful poll touches the liveness file — so a fail-closed or halted collector goes stale | Read the log. version mismatch (409) → --update; re-enroll required → a fresh token. |
--update says already in step while nothing is collected | Pre-1.2.7 core: it dropped its version header from the refusal | Read the version on the core, then --update --version <ver>. |
| Uninstall refuses | The outbox still holds results the core never accepted | Let it drain, or --uninstall --force to accept the loss. |
| Collect now feels slow at one site | A middlebox is cutting the ~25 s held long-poll, so the collector fell back to its poll interval | Allow the idle connection through, or accept the slower cadence — collection itself is unaffected. |
| Collector reports re-enroll required | Its identity was revoked, or sustained auth failures | Issue a fresh token and re-run the join; it won’t self-generate a new identity by design. |
| Collections auth-fail | Wrong/again-locked device credential | Check the source’s credential; auth failures aren’t retried (to avoid device lockouts). |
Related
Section titled “Related”- Collectors — embedded vs standalone, health and enrollment concepts.
- Virtual appliance — deploying a collector as an appliance rather than a container on your own host.
- Tracked configs & transports — pointing sources at your collector.
- Bulk onboarding — onboard a whole site through the new collector.
- Credentials & the vault — the just-in-time credentials handed to the collector.